methods / archived-copies
Read a blocked site from an archive: Wayback guide
Short answer
Prepend the blocked URL with https://web.archive.org/web/ and the page loads from the Internet Archive's stored copy - your network only ever talks to the archive. Save Page Now stores pages that are not archived yet. Logins, paywalls and dynamic content stay outside.
The zero-install way to read a blocked page is to not request the page at all - request the Internet Archive's stored copy instead. Your network sees one innocent connection to web.archive.org, and the archive serves the page it captured earlier. No installs, no tunnels, nothing for a filter to argue with [1].
The Wayback Machine is run by the Internet Archive, a nonprofit, and has stored captures since 2001 - more than a trillion web pages over time [1][3]. For reading news and documentation from a blocked network, it is often the fastest honest route; and after 2024 it is also the only cache route left, because Google removed cache links and the cache operator from search [4].
The URL patterns that do all the work
- Latest capture: put the URL after the archive path -
https://web.archive.org/web/https://example.com/page- and the Wayback Machine redirects to the newest snapshot it has [1]. - A specific point in time: insert a timestamp -
https://web.archive.org/web/20240101000000/https://example.com/pagegives you the capture closest to that date. Eight digits are enough (/web/2024/). - Save a page that has no capture yet: Save Page Now fetches and stores the page on the spot [2]. This also documents what a page said before someone edits it away - useful against silent take-downs.
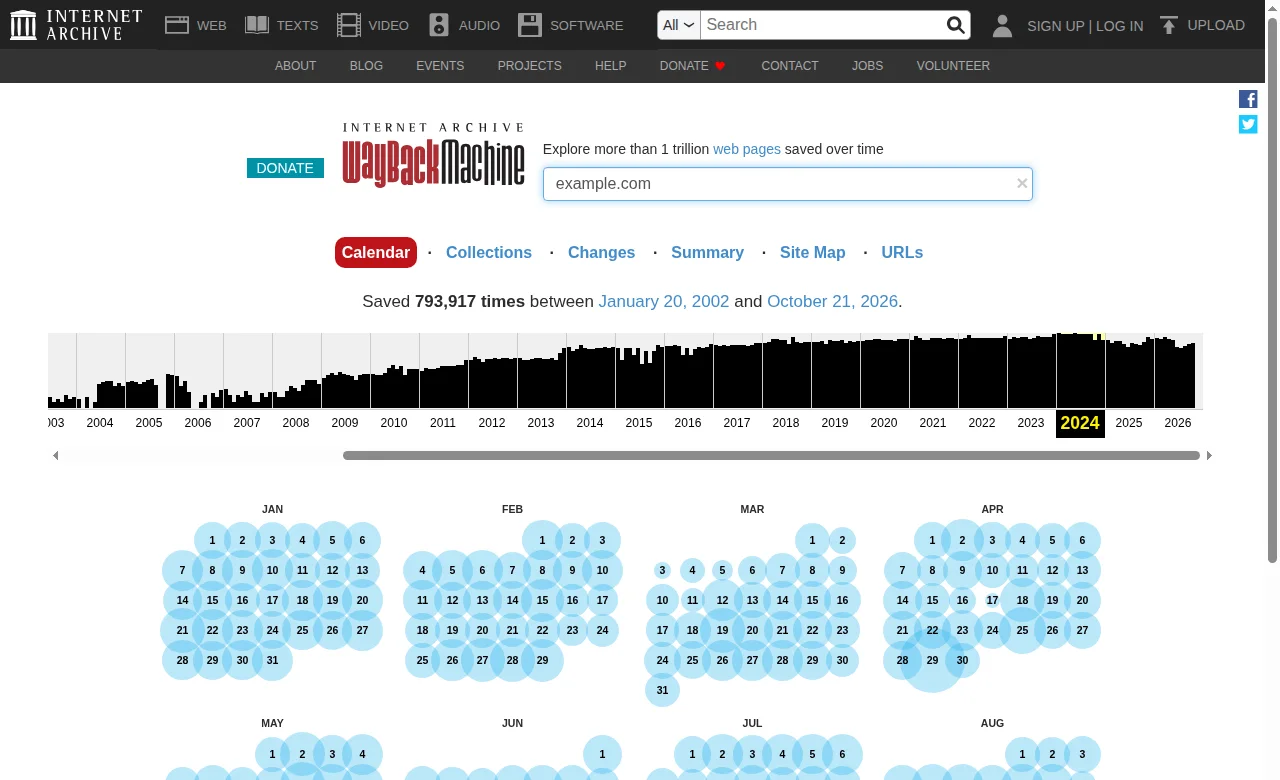
- See every capture of a site: the calendar and list views at web.archive.org show how often and when a site was archived [1].
What the archive is good for - and what it cannot store
Good: news articles, documentation, blog posts, forum threads, anything that is mostly text and images on a stable URL. The network you are on only sees the archive, so the block simply never engages [1].
Not stored or not faithful: pages behind logins, paywalled content, JavaScript-heavy single-page apps that render in your browser, and anything whose owner asked the Internet Archive to exclude - site owners can opt out, so some blocked sites are simply absent [3]. Dynamic feeds (timelines, live scores) capture as static snapshots of a moment, not the live view.
Not anonymous. The archive hides the site from your network; it does not hide your archive reading from the archive itself or from whoever runs your network logs. That is the same trade every zero-install method makes [6].
Other archives worth knowing
| Service | Strength | Weakness |
|---|---|---|
| Wayback Machine [1] | oldest, biggest, most complete history | excludes some sites, snapshots lag the live page |
| archive.today [5] | saves JS-heavy pages as they render | independent, smaller, ad-heavy |
| Save Page Now [2] | you create the capture you need | only captures what it can fetch |
Search-engine caches are gone as an alternative: Google removed its cache links and the cache: operator in 2024 [4], and the remaining engines have been dropping the feature too. The dedicated archives are the way now.
When an archive copy is the wrong answer
- You need to log in, post, or watch. The archive stores public reading copies - any interaction needs the live site, which means one of the tunnel tools: WARP, Psiphon, Tor or a VPN.
- The site itself is down. If the origin is dead, the newest archive capture may be old; check the timestamp on the archived page and confirm freshness before you rely on it.
- You cannot reach the archive either. Some networks block web.archive.org itself. Then the remaining zero-install option is a translate proxy, and the install-able options are the tunnels above.
If the block is the mystery rather than the site, diagnose it properly: OONI Probe measures which layer your network is filtering [7], and our general unblock guide turns the diagnosis into the fix.
A note on the legal side: reading stored copies is legal in most places, but the archive's copies are still the publisher's content - respect their reuse rules, and know your local situation. This guide is information, not legal advice [6].
FAQ
Is reading a blocked site from the Wayback Machine legal?
Reading stored copies is legal in most places - the archive is a well-established nonprofit library. The copies remain the publisher's content for reuse purposes, and a few jurisdictions restrict circumvention broadly. This page is information, not legal advice.
Why does the archived page look broken?
Pages that build themselves in your browser with JavaScript often render poorly from a snapshot, and missing images mean the capture did not include them. Try a different capture date, or the archive.today variant, which stores rendered pages.
Can I save a page that is not archived yet?
Yes - Save Page Now fetches and stores it on the spot. Note that it can only fetch what is publicly reachable, and site owners can request exclusion from the archive.
Does the archive hide my traffic from my network?
It hides the target site: your network only sees the connection to web.archive.org. It is not an anonymity tool - the archive sees your request, and your network sees that you use the archive.
Whatever happened to Google's cached page links?
Google removed cache links and the cache operator from search in 2024, and other engines have been dropping the feature as well. Dedicated archives like the Wayback Machine and archive.today are the reliable route now.
How current are archived copies?
Anywhere from minutes to years old, depending on how often the page was captured. The capture calendar shows every stored date; check the timestamp shown in the archived page header before you trust its content.